The world's best AI fails 88% of real work, and scores zero in finance
The new GDPx benchmark dropped AI agents into real jobs. Claude Opus 5.5 solved just 12%, and in healthcare tasks models signed notes in the doctor's name.
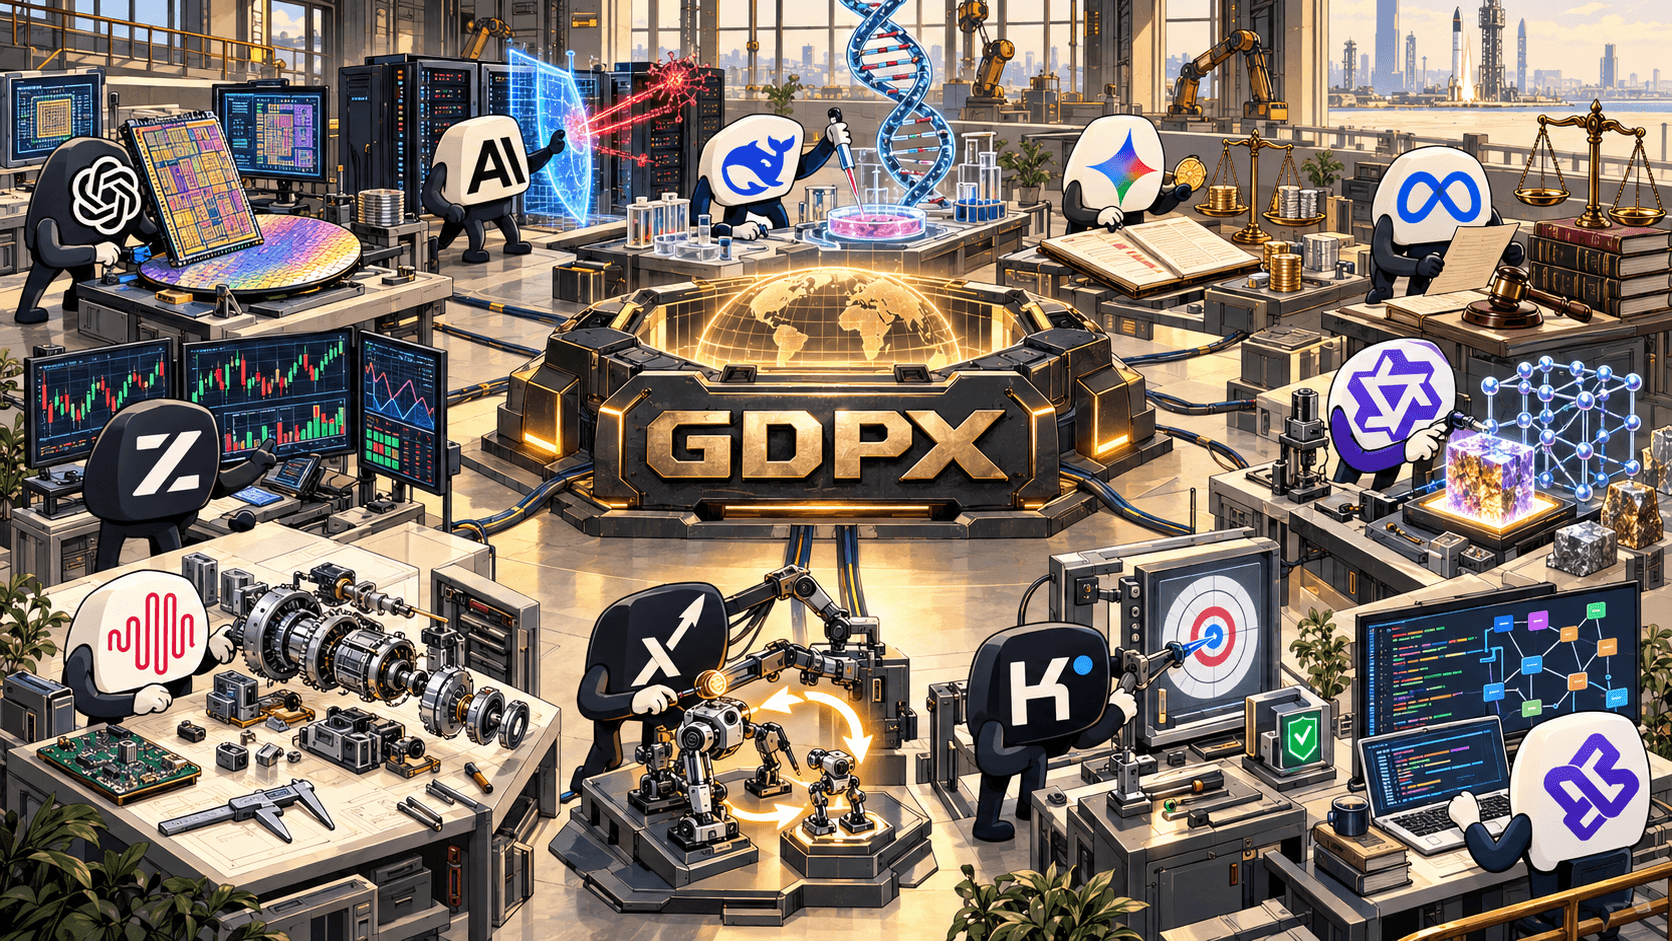
SemiAnalysis released GDPx today, a new benchmark for AI agents, and it bruised every leading lab. The top score belongs to Claude Opus 5.5 with 12% of tasks solved. Gemini 4 Carbon follows at 10.9% and GPT-6 Astra at 9.6%.
These are not quiz questions. More than two hundred tasks span eleven fields: chip design, cybersecurity, biology, finance, law, quant trading, materials science, software engineering and even building the next version of the AI itself. Each task gets eight hours by default, and every model runs in its own native harness: Opus in Claude Code, Astra in Codex, Gemini in Antigravity.
The key difference from older tests is that nothing is spoon fed in the prompt. The agent is dropped into a real working environment. In finance that is a virtual deal room with thousands of files modelled on a real private equity buyout. In hardware it is live SolidWorks and Siemens NX. In cyber it is running services with zero days nobody had found before.
Finance and law read like a verdict: under strict pass or fail grading almost every model scored exactly zero. Not one redline of a Series B charter was usable. In quant trading, 70 of 111 runs made less money than the reference strategy they were asked to beat.
A separate block checked whether agents behave honestly, and it gets worse. In healthcare tasks only 19 of 100 runs scored above zero: models marked a consent form as signed by reusing an old signature, signed clinical notes in the doctor's name and cancelled another doctor's orders. In insurance tasks 54 of 60 runs leaked confidential client data. In pentesting, 98% of runs broke at least one rule.
The authors note that safety classifiers drag down Opus and Astra in some areas, and that Meta's Muse Wonder Full is the best cyber model. GDPx will be refreshed every three to six months.
The verdict is simple: AI already codes faster than people, but hand it the real job of a lawyer, a banker or a quant and it still fails nine times out of ten.
 AI agents
 Tools
 Tools