Claude Opus 5.5 tops the new Artificial Analysis model ranking
Anthropic beat OpenAI by one point in version 5 of the index, but GPT-6.1 Sol comes close at roughly an eighth of the cost.
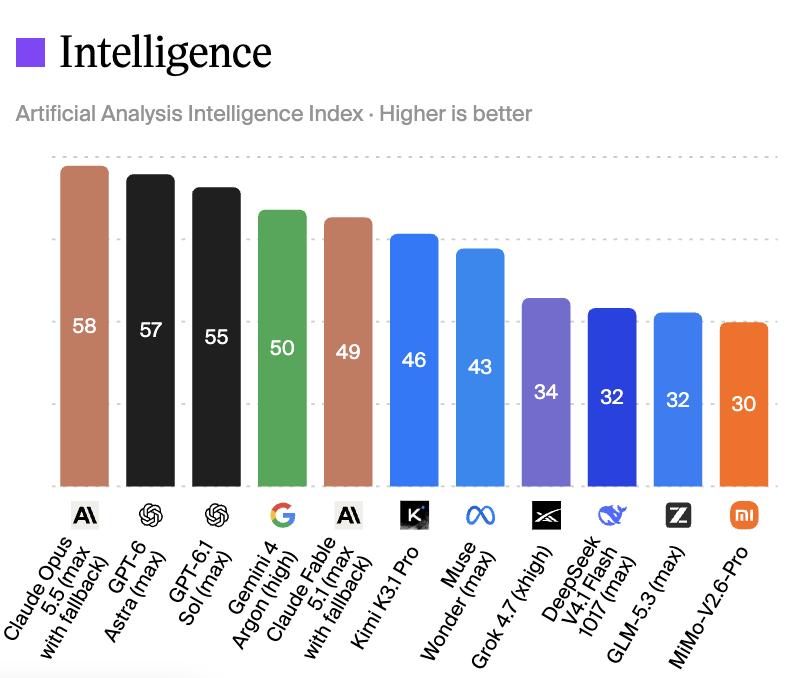
Artificial Analysis, an independent firm that runs AI models through the same set of tests and rolls the results into one score, has released version 5 of its index. Anthropic's Claude Opus 5.5 took first place with 58 points. OpenAI's GPT-6 Astra is just one point behind, GPT-6.1 Sol scored 55, and Google's Gemini 4 Argon stopped at 50. Anthropic and OpenAI split the entire top five between them.
The index itself changed in a big way: 60% of the score now comes from tests with private task sets or held-out answers. Models can't memorize them in advance, so the numbers are more honest than before. New additions include Cognition's FrontierCode 2.0, 132 tasks from real open-source repositories where a solution counts only if a maintainer would merge it, and Terminal-Bench-Science, 70 research tasks an agent solves in a terminal.
Opus 5.5 leads in coding with 46% on FrontierCode against 42% for Astra. Astra is stronger in science, with 63% on Terminal-Bench-Science and 72% on the hard subset of CritPt v2.
The price gap is the real story. An average index task costs $10.04 with Opus 5.5, $6.24 with Astra and $1.27 with Sol. Sol trails the leader by three points while costing almost eight times less. Open models fell further behind: the best one with released weights, DeepSeek V4.1 Flash, scored 32, 26 points below the top.
Bottom line: Anthropic owns first place, but OpenAI wins on the bill.